What Agentic Studio actually does
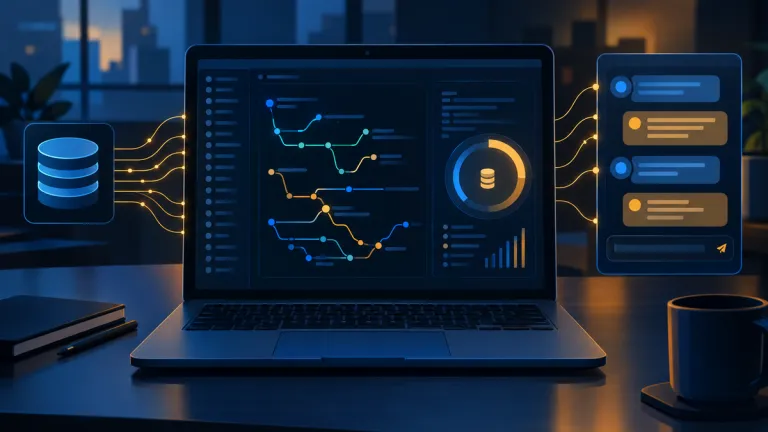
The product is a chat layer on top of LinearB's existing delivery intelligence. A manager types a question and gets an answer assembled from code ownership, rework history, service incidents and complexity metrics, without building a dashboard first. The same data is exposed to coding agents through a Model Context Protocol server, so an MCP-capable assistant can check who owns a service and what broke there last quarter before it edits a file.
MCP is the open interface that most major coding tools now speak, which makes this a distribution play as much as a feature. LinearB does not have to build its own agent. It only has to be the source of context the agent reads.
The effort skill, still in early access, is the part with real engineering behind it. LinearB describes it as a way to calibrate how many tokens an agent burns and how deep its edits go against three inputs: code risk, business relevance and past incidents. In practice, an agent should make a small, cheap change in a payment service it has already broken twice, and can afford a broader rewrite in a test utility nobody imports.
The data LinearB is building on
The launch numbers come from LinearB's analysis of 2.7 million pull requests across 83,000 developers at 253 organisations, plus a separate LinearB-published benchmark of 8.1 million PRs from 4,800 teams in 42 countries. Both are vendor-published data, and the same caveat applies: the samples are LinearB's own customer base, which skews toward teams that already buy delivery analytics. The direction, though, matches what other vendors and internal engineering reports describe.
Three findings carry the argument:
- Developers who used AI on at least 75% of coding days merged 96% more pull requests year over year. Developers who used no AI merged 3.6% fewer.
- At the 75th percentile, AI-assisted PRs were 2.6 times larger than unassisted ones, and agent-opened PRs waited more than five times longer for review.
- In top-performing organisations, 79% of agent PRs merged within 30 days, against 92% for human-written code. In lower-tier organisations the agent figure dropped to 37%.
Agents opened 4.7% of pull requests at high-adoption companies, while AI helped author up to 54% of PRs at the best-performing ones. AI-assisted review added up to 5 percentage points to merge rates. More code is arriving; the gate in front of it has not widened at the same speed.
What $35.20 per developer day buys
LinearB puts 90th-percentile token spending at $35.20 per developer per coding day. Median spending stayed roughly flat, and that split matters: the average team does not have a bill problem; the heavy users do. Upper-tier token spending rose nearly 75% in three months.
| Output price per 1M tokens | Output tokens $35.20 buys |
|---|---|
| $0.25 | ~140.8M |
| $1 | ~35.2M |
| $5 | ~7.0M |
| $15 | ~2.3M |
This is arithmetic, not a recommendation. Real agents mix input and output tokens, cached reads and several models in one session, so the counts differ. The spread is the point: the same daily budget covers roughly 140 million output tokens at the $0.25 band or 2.3 million at the $15 band. The price band, not the tooling, sets the order of magnitude.
Run it forward. At 21 coding days a month, $35.20 becomes about $739 per developer, roughly €684 at 1.08 dollars to the euro, before tax. A ten-person team sitting at that percentile is looking at around $7,400, or €6,850, a month in tokens alone. We track input and output pricing per million tokens on our own rig in the AI Arena for exactly this reason; a number quoted in dollars per day hides which side of the token split is growing.
Review capacity is the tighter constraint
The merge-rate numbers suggest the bottleneck is human attention, not generation. Agent PRs that are 2.6 times larger take longer to read, and a reviewer who cannot tell a risky diff from a routine one will treat both the same way. Context is what shortens that decision. LinearB cites Kraken as an early MCP user; that is one company's account, not a controlled trial.
European questions the announcement leaves open
The launch statement does not name an EU hosting region, a data residency option or a processing location for the MCP server. For a European engineering organisation, that matters more than the feature list, because code metadata, incident reports and ownership graphs are all personal data in some contexts and commercial secrets in all of them. Three checks belong in any procurement review:
- Whether the MCP server is hosted by LinearB or runs in the customer's own infrastructure.
- Which model providers receive the context payload, and under which data processing agreement.
- Whether prompts and returned context are logged, and for how long.
Regulation adds a paper trail. General-purpose AI obligations under the EU AI Act have been enforced directly since August 2025, and Article 50 transparency rules, covering disclosure and synthetic-content labelling, have applied since August 2026. A delivery analytics product is not itself a general-purpose model, but it sits between European buyers and the models they call. Procurement teams now ask which model handled a query and what documentation the provider publishes. LinearB's answers to those questions will decide more European deals than the effort skill will.
Pricing is the other gap. The company frames Agentic Studio as available to all LinearB customers, which points to inclusion in existing subscriptions rather than a separate line item. Nothing published confirms that.
Does Agentic Studio replace code review or a DORA metrics dashboard?
No. It queries and packages the data LinearB already collects, then hands it to a human or an agent. The review still happens in your Git platform, and the merge decision stays with your team.
What does an MCP server change for a coding agent in practice?
It gives the agent a callable source of repository context instead of guessing from the open files. Whether that improves output depends on the agent and on how well the returned context is scoped; a large context dump is not automatically better than a small one.
Is the effort skill available now?
It is in early access, according to LinearB. There are no published measurements yet of how much token spend it saves or how much it changes merge rates.
That last point is the limit of today's announcement. The effort skill is a design argument backed by LinearB's own benchmark data, not a measured result, and the vendor has not published a before-and-after token bill from a customer running it.