META-IR stands for Meta-Introspective Reasoning for Adaptive Safety Alignment in LLM. The paper comes from a team led by Mahabubur Rahman Miraj (per the arXiv submission record). The paper is an arXiv preprint (arXiv:2611.10089v1, submitted 6 Nov 2026) accepted at ICME 2026 in Bangkok, 6 pages, 5 figures, per the arXiv listing.
Inside META-IR
Most alignment stacks combine supervised fine-tuning, preference data and a refusal policy. The model learns patterns of prompts that should trigger a no. The weakness is obvious: a new phrasing, a role-play wrapper or a multilingual detour can move the prompt outside the learned refusal pattern.
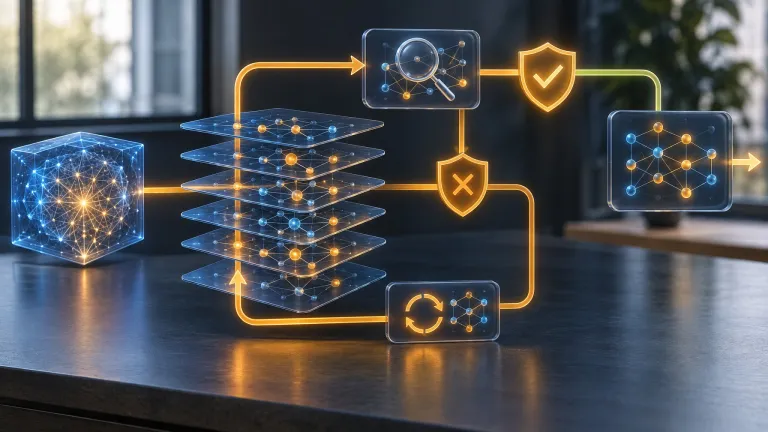
META-IR adds a second process inside the model's reasoning. According to the paper, it uses a dual-loop architecture. The inner introspective loop performs structured risk analysis, self-assessment and reflective correction via SI-MCTS. The outer meta-learning loop optimises the introspection policy across diverse jailbreak task families so the model can generalise to unseen attacks. A dynamic jailbreak simulation module exposes the model to progressively harder adversarial prompts, enabling continual self-improvement without human supervision. The authors position this against static chain-of-thought introspection methods and against external red-teaming games that need repeated human annotation.
The paper frames the method as adaptive safety alignment. A model does not simply learn a longer list of forbidden prompts. It learns a way to review its own reasoning during a request. That distinction matters because jailbreak attempts often work by making a harmful request look like a normal task. A safety check that looks only at the final answer may miss the point where the model talks itself into the harmful part.
Reported results and limits
The authors report that META-IR substantially improves adaptation speed, robustness and reasoning stability compared with all baseline models across safety, helpfulness, generalisation and introspection metrics. The experiments cover Llama-3.1-8B-Instruct and Qwen-2-7B-Instruct. The abstract does not give a single percentage that would let a buyer compare it with a commercial moderation API. The result is a preprint claim. Independent replication would need the same prompts, the same base models and the same refusal thresholds. Without those, the number is not a procurement benchmark.
There is also a cost question. The paper is open access, so reading it costs €0. That says nothing about inference cost. A meta-introspective loop can add tokens, latency and memory pressure. If the model writes extra safety reasoning before each answer, the serving bill goes up. The paper's focus is alignment quality, not throughput. We have not run META-IR in AI Arena, so I am not quoting tokens per second or VRAM figures for it. Any production test should measure those numbers on the target hardware first.
The authors also do not present META-IR as a replacement for moderation filters. It is an alignment method. It can reduce the chance that a model follows a jailbreak. It does not inspect every uploaded file, block every toxic string or provide a human review queue. Those parts of a production safety stack remain separate.
European compliance still needs more than alignment
For European teams, the timing has two layers. General-purpose AI obligations under the AI Act applied from 2 August 2025. The Article 50 transparency duties, including disclosure of AI-generated content and machine-readable marking, became binding on 2 August 2026. The EU AI Office also has direct enforcement and penalty powers over general-purpose AI providers. Under the AI Omnibus, Annex III high-risk obligations are now set for 2 December 2027, while Annex I embedded systems are set for 2 August 2028.
META-IR sits before those obligations. A better refusal policy can reduce the chance that a model produces harmful content when someone tries a jailbreak. It does not watermark an output. It does not produce the technical documentation a provider needs. It does not replace incident logging or human review. A European company could use the paper as part of an internal safety evaluation, especially for models hosted in the EU. The compliance file still needs the Article 50 controls and the risk-management evidence that the AI Act requires.
The open-access nature helps smaller teams. A startup in Prague, Brno or Berlin can read the method and test the idea without a licence fee. The paper links source code at github.com/Miraj-Rahman-AI/Meta-IR, but it does not announce a hosted API, a production SDK or released model weights. Treat it as research that can inform a test plan, not as a drop-in filter. The European Commission's regulatory framework for AI is the place to check current deadlines and obligations.
META-IR against current model releases
Among current model releases, the comparison set here is narrow: OpenAI's GPT-6.1 Terra and Mistral Large 4. META-IR is not a competitor to those APIs. It is a training and reasoning approach that a model builder could add to an alignment pipeline.
Mistral Large 4 is the obvious European comparison point because its weights are released under the Mistral Ecosystem Open-Weight License. A European team that runs open-weight models can inspect the base model and add safety layers. A closed API user cannot. That difference matters for auditors. Open weights make it easier to test a method like META-IR on the same base model. They also make it easier to break the model in ways the vendor did not plan for.
Testing the paper in a real stack
Read the method, then build a small test. Pick one open-weight model you already serve. Collect a set of jailbreak prompts from your own logs, with personal data removed. Compare the base model's refusal rate with a version that uses an external safety check and a version that imitates the META-IR loop. Measure false refusals as well as successful jailbreaks. A safety layer that blocks too many normal requests will lose users, and the paper's headline robustness claim does not answer that trade-off.
Keep the evaluation in the EU if data residency matters. Run the prompts on your own hardware or on an EU-hosted API. Log the model version, the prompt set and the refusal policy. That record is more useful than a single score from a preprint. It also gives you something to show a customer or a regulator if a deployment is questioned.
Is META-IR available as open-source code?
The paper links source code at github.com/Miraj-Rahman-AI/Meta-IR, but it does not announce a hosted API, a production SDK or released model weights. Treat META-IR as a research method that can inform an internal test, not as a ready-made library.
Does META-IR replace content moderation?
No. It is an alignment and reasoning approach. It can help a model resist jailbreak prompts, but it does not replace watermarking, output logging, abuse reporting or human review. Those controls are separate parts of a deployment.
Can European companies use it for AI Act compliance?
They can use the paper as part of an internal safety evaluation. It is not a compliance certificate. Article 50 transparency duties, technical documentation and risk-management evidence still have to be met by the deployer or provider.